


Original PDF
Scanned document, multi-column layout, complex table structure
Self-hosted PDF Conversion SDK
Add document conversion to your product without building the parsing, OCR, and output pipeline yourself. Validate editable Office files, Searchable PDF, JSON, and Markdown with your own documents before integration.
Start with the formats that decide whether the SDK fits your product: editable Office files (.docx, .xlsx, .pptx), Searchable PDF, JSON, and Markdown, each testable with your own documents.
Editable Word (.docx) files with paragraphs, lists, headers, footers, images, and page structure.
Excel (.xlsx) output for tables, merged cells, multi-page tables, and spreadsheet-ready structure.
PowerPoint (.pptx) output with slide-ready layout, images, text, tables, and visual structure.
Preserve the visual page and add a searchable text layer for search, selection, copy, indexing, and review.
Layout-aware JSON for RPA, RAG, enterprise search, validation workflows, and table extraction.
Reading-order Markdown with headings, tables, and page context for knowledge-base workflows.
Compare original PDFs with PDFSolid output using your own documents or sample files to check layout, tables, OCR text quality, and reading order.
Scanned document, multi-column layout, complex table structure
Editable Word with recovered text, tables, and formatting
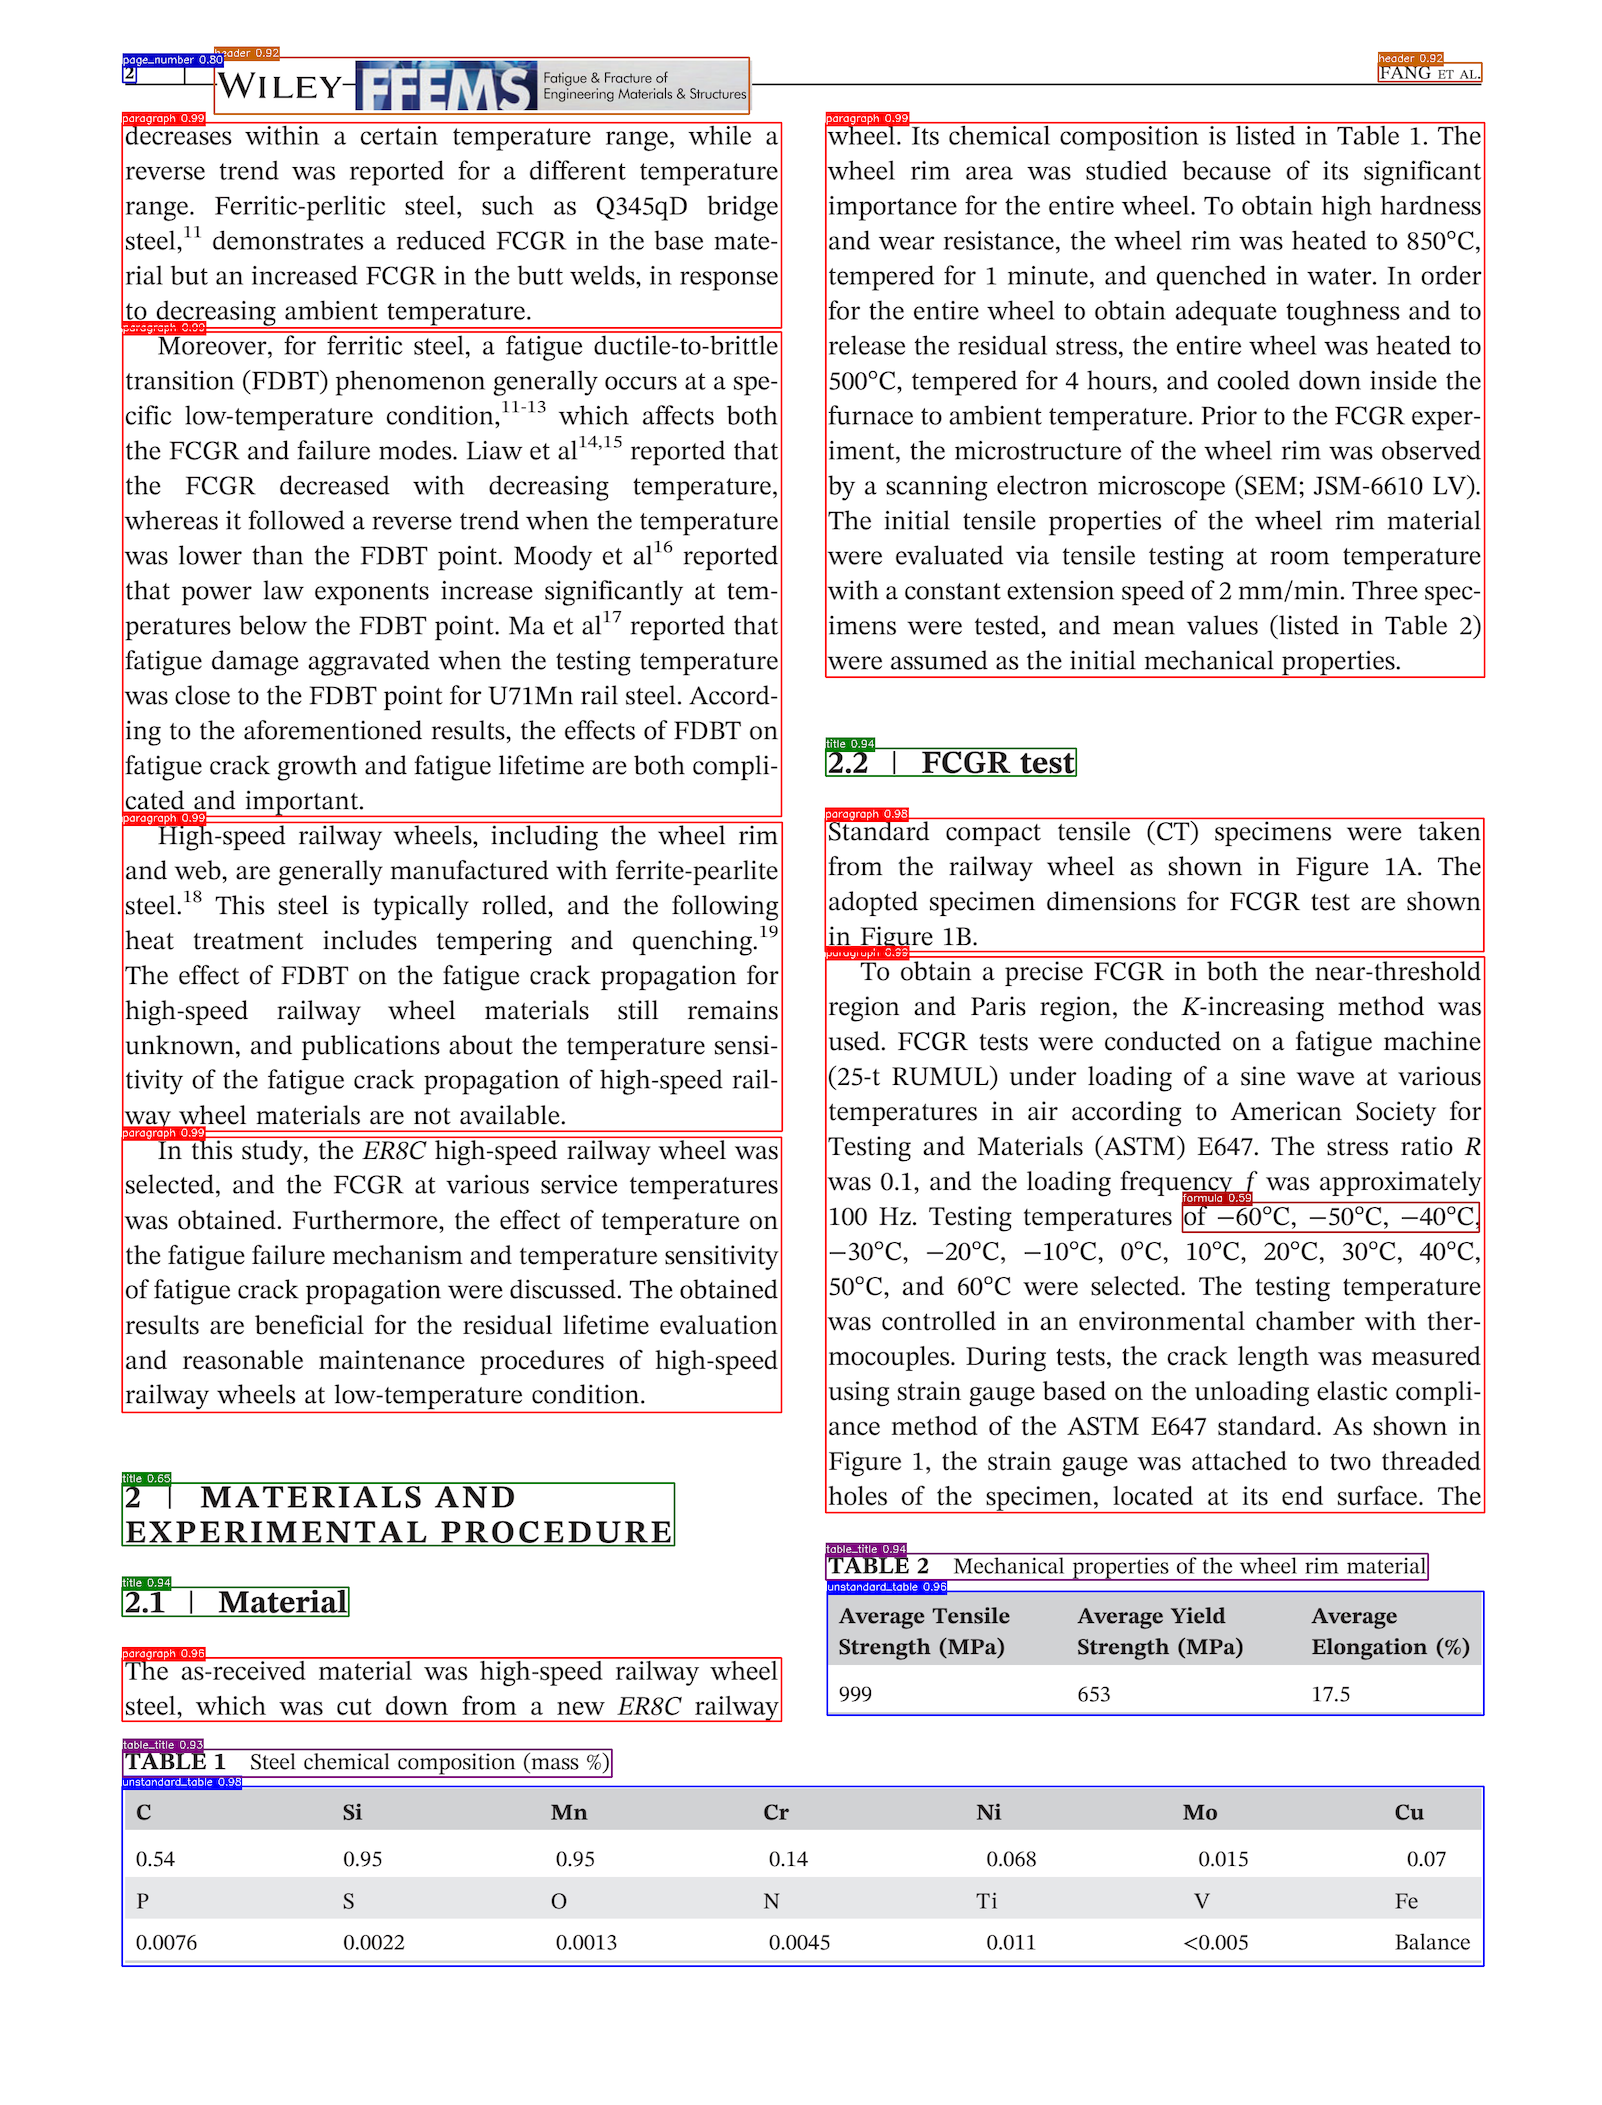
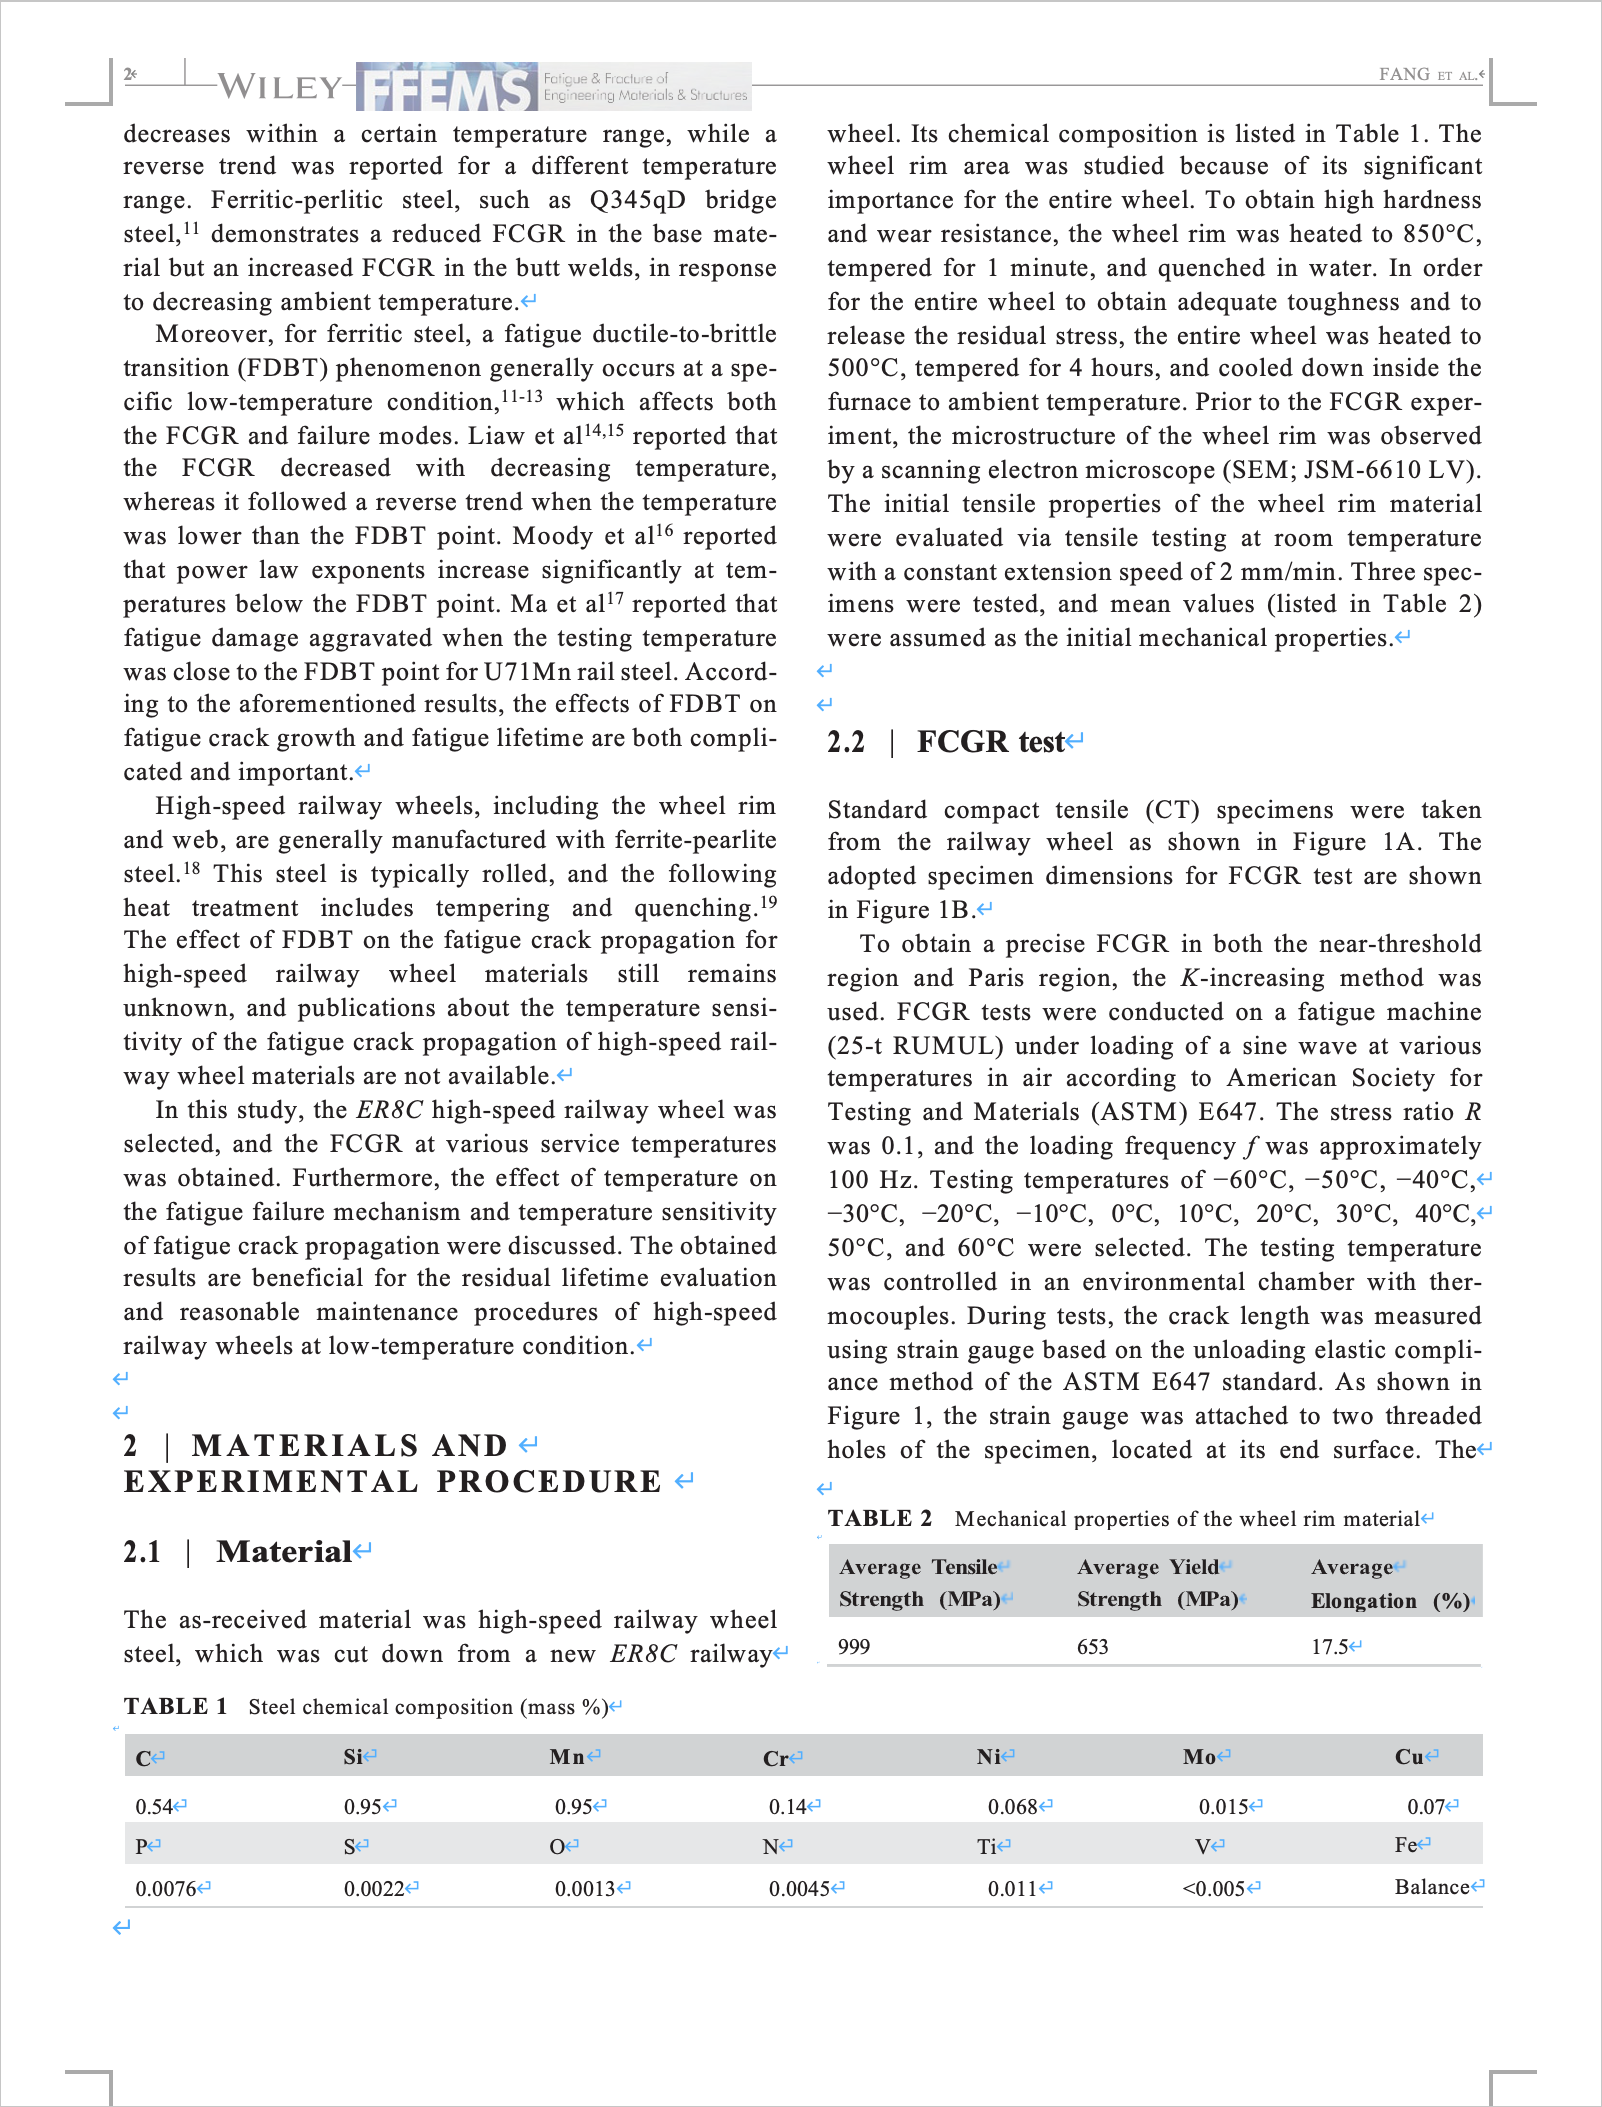
PDFSolid detects titles, headings, columns, tables, figures, forms, and reading order before rebuilding Word, Excel, PowerPoint, Searchable PDF, JSON, or Markdown output.
Recover logical reading order across columns, captions, footnotes, headers, and page-crossing paragraphs.
Recover text from scanned pages before editable Office file conversion, Searchable PDF generation, or structured output.
Rebuild rows, columns, merged cells, and multi-level headers for Excel, CSV, JSON, and Markdown.
Detect figures, labels, forms, checkboxes, signatures, annotations, and dense page regions where source quality allows.
Detect titles, heading levels, paragraphs, columns, rows, lists, tables, figures, formulas, code blocks, headers, footers, page numbers, watermarks, and reading order.
Recover text from scanned PDFs and images before Searchable PDF generation, editable Office file conversion, or structured extraction. Validate OCR and layout quality with your own files.
Use the same SDK workflow across Linux, macOS, Windows, backend services, desktop apps, and batch jobs.
| Platform | Languages |
|---|---|
| Linux | C, C++, Java, Python, Go, PHP, Ruby, Node.js |
| macOS | C, C++, Java, Python, Go, Objective-C |
| Windows | C, C++, Java, Python, Go, .NET |
Developer guides
Support PDF/A archive, PDF/X print exchange, PDF/E engineering, and PDF/UA accessibility-ready PDF workflows.
Archive-ready PDF output for long-term preservation and compliance workflows
Print-ready PDF exchange with standardized color and output intents
Engineering PDF output for technical documents and CAD drawing workflows
Accessibility-ready PDF output for universal access workflows
Run the live demo for a quick output check, then start a free 30-day trial to test the SDK with your real documents.


